
Marxen Data Labs
Compute is purchasable.
Reach is not.
Close to 500,000 verified contributors across India, Nepal and Sri Lanka. Speech, text, document, image, egocentric and multimodal sensor data, gathered by people who are physically there.
01
Why this is the hard part
Everyone building a model needs the same thing: more data, from more of the world, collected and consented properly. The bottleneck is not annotation software. It is reach.
A clean hour of code-switched Tamil and English speech from a 52-year-old bus conductor needs someone standing in front of that bus conductor, explaining what the recording is for, taking real consent, capturing usable audio in a noisy depot, and paying him the same day.
Our network was built over years for ground activations and campus programmes. It was engineered to put trained people in front of strangers at scale, and we repointed it at data.
Contributors are identity-verified, briefed, trained and paid, which is what separates a corpus you can attest to from one assembled by anonymous accounts optimising for volume.
02
What we produce
Stream bank · shotgun microphone 
Field recorder · steel table 
Mixing console · three faders 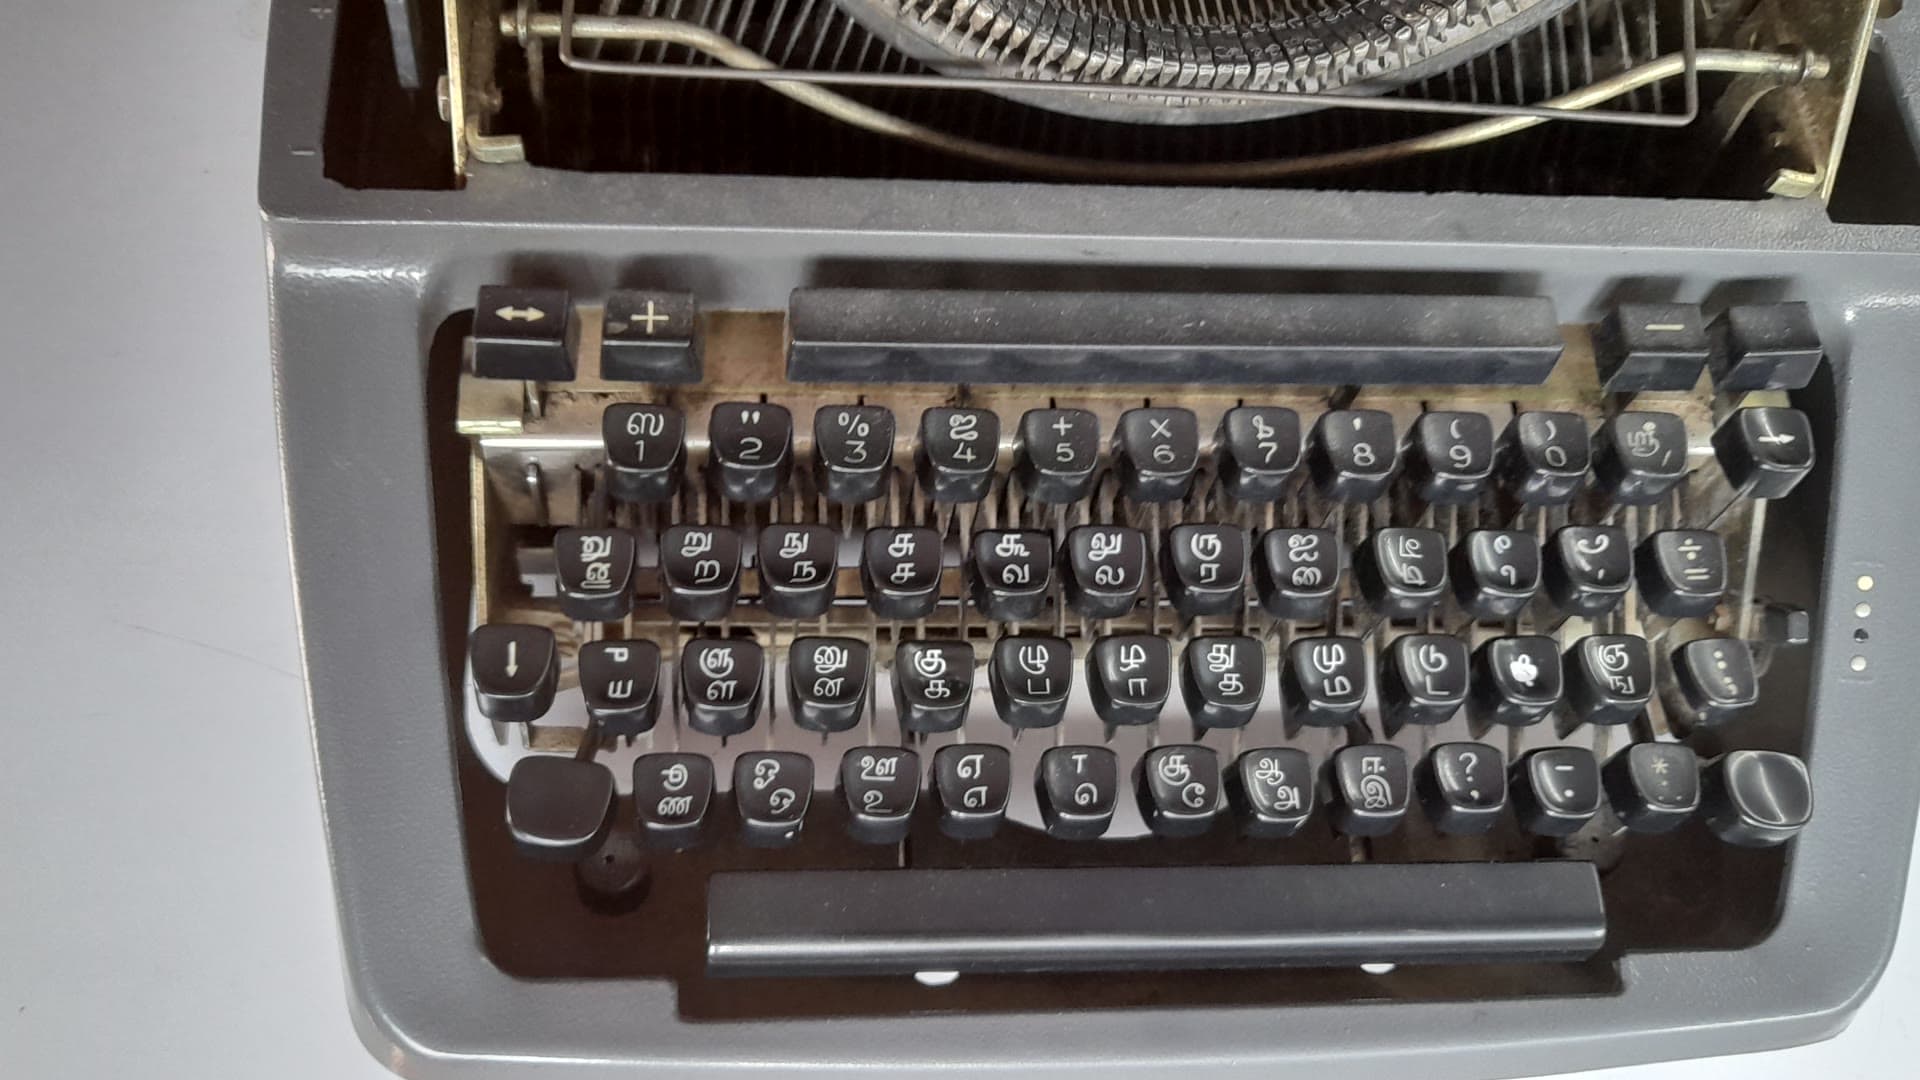
Typewriting institute · Tamil keyboard 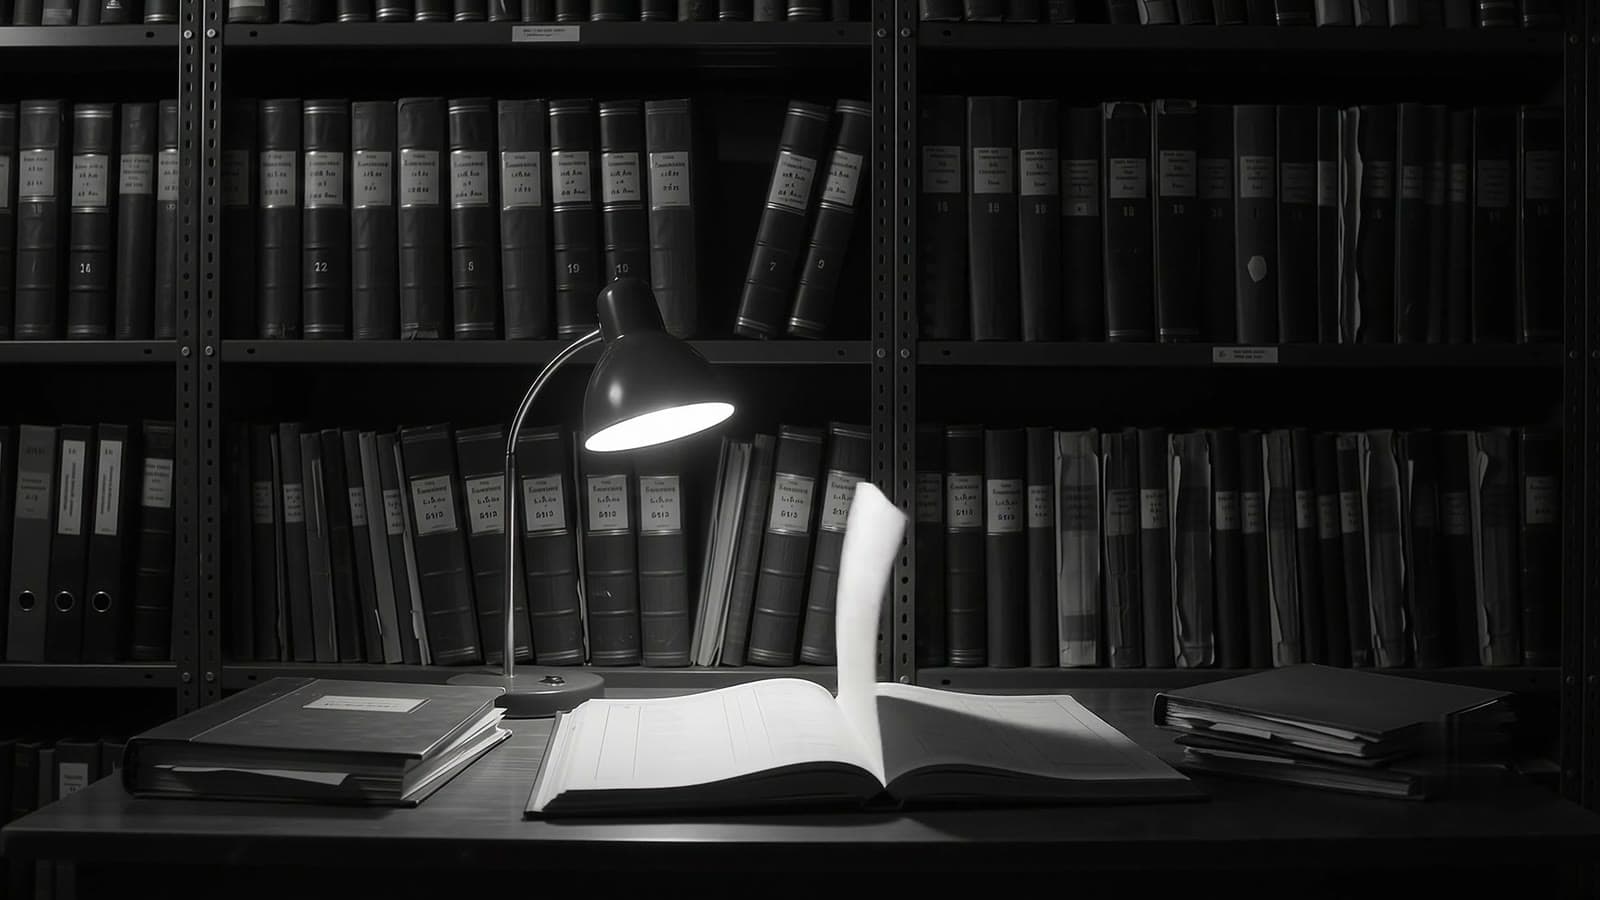
Records room · registers, open volume 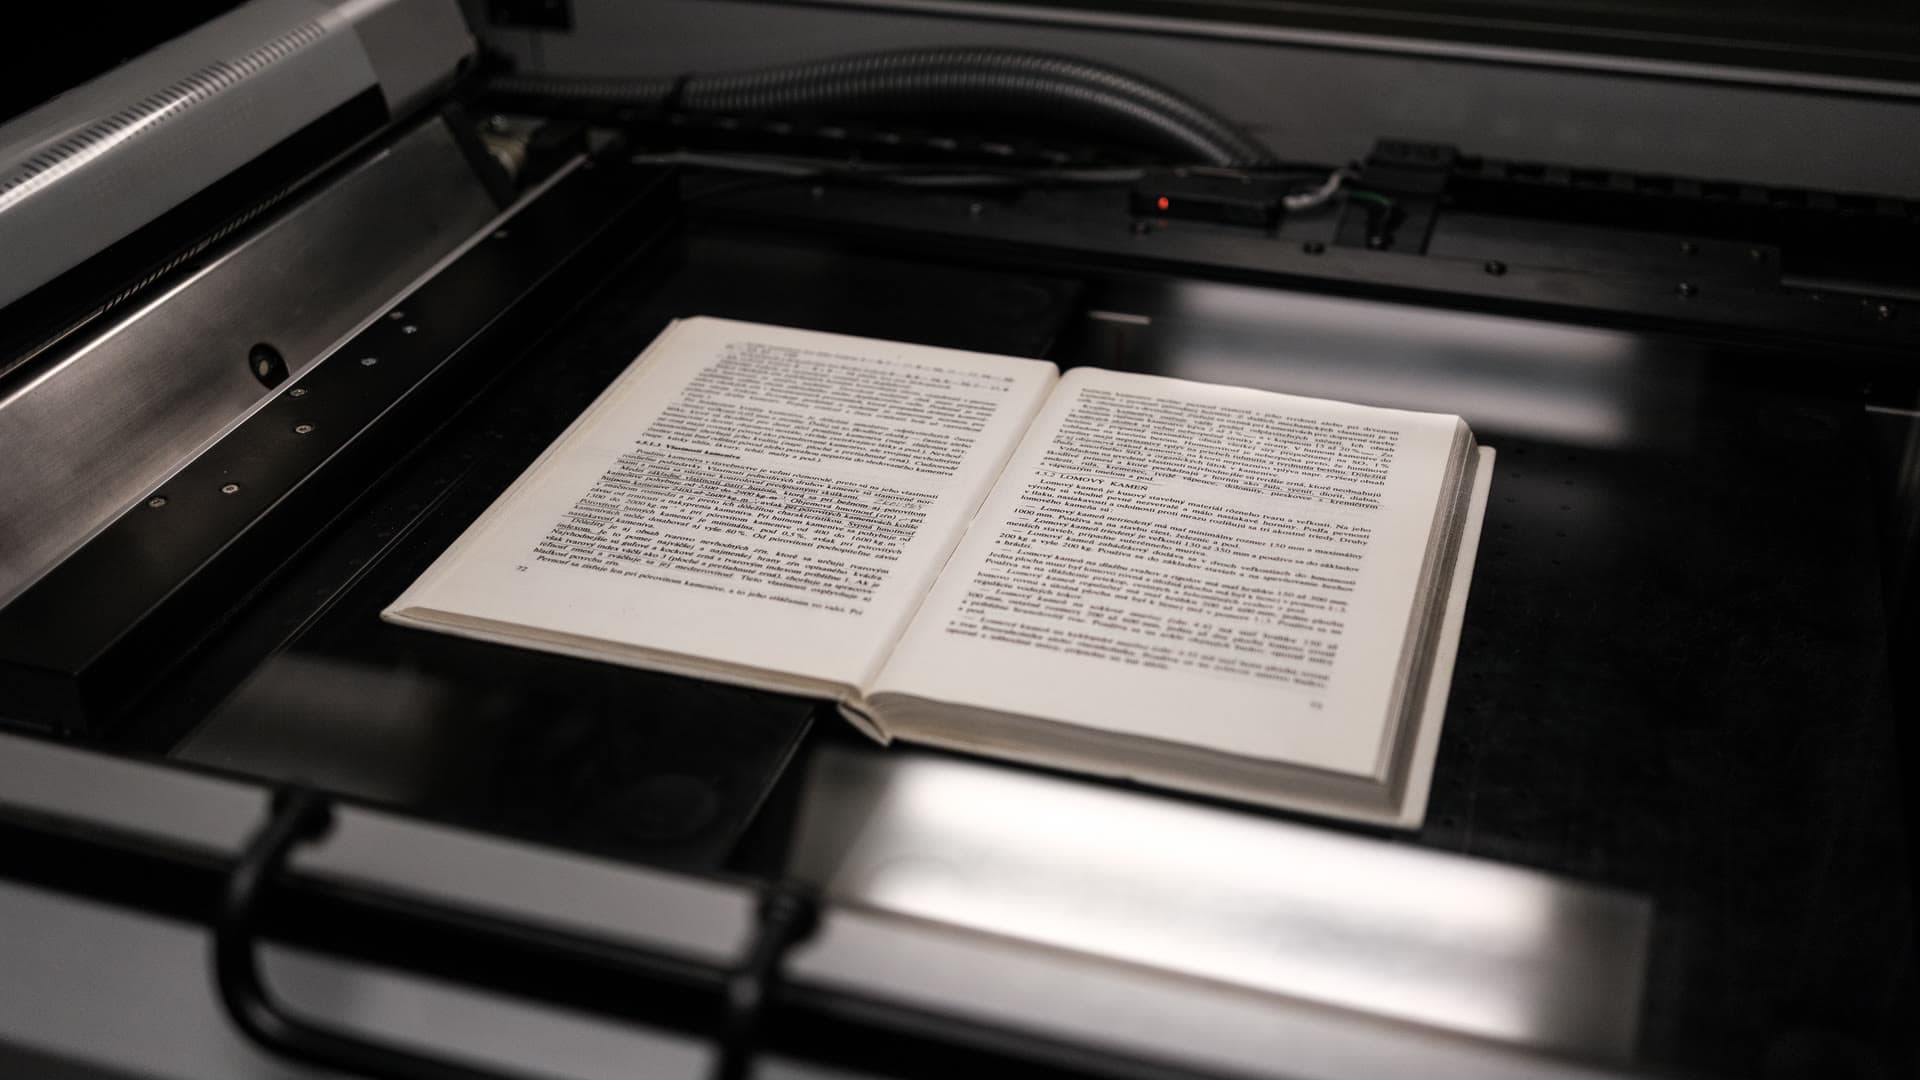
National library · book scanner 
Head-worn camera · spectacle frame 
Loading bay · pallet truck 
Car roof · lidar and camera pod 
Stereo depth camera on its mount 
Record library · numbered volumes 
Server hall · corridor
04
How we work
Human-led annotation with structured QA. Not a crowd marketplace, and not a model labelling its own training data. Every workflow leaves an audit trail: who labelled what, against which version of the guidelines, at what inter-annotator agreement.
Consent is explicit, recorded and revocable, with the terms written in the contributor's own language. Contributors are paid on schedule and told what the data is for. For a regulated buyer that is the difference between a corpus you can train on and one your counsel makes you delete.
05
Who buys this
Frontier and foundation-model labs adding multilingual capability. Indian AI companies fine-tuning on domain data. Enterprises building on their own historical material. Government language-infrastructure programmes. Robotics teams that need egocentric and sensor data from environments that look nothing like a California office.
03
Coverage
- verified contributors
- Close to 500,000
Indian languages.
Tamil, Hindi, Telugu, Kannada, Malayalam, Bengali, Marathi, Gujarati, Punjabi, Odia, Assamese and Urdu, plus the code-switched registers that sit between them and English.
Geographies.
India across all major states, plus Nepal and Sri Lanka.
Built in India. For the people actually using it.
Tell us what you are trying to do. Bring the use case, the constraints and the users. We will tell you honestly whether Marxen is the right call, including when the answer is no.